Case study · Full stack
LLM monitoring dashboard
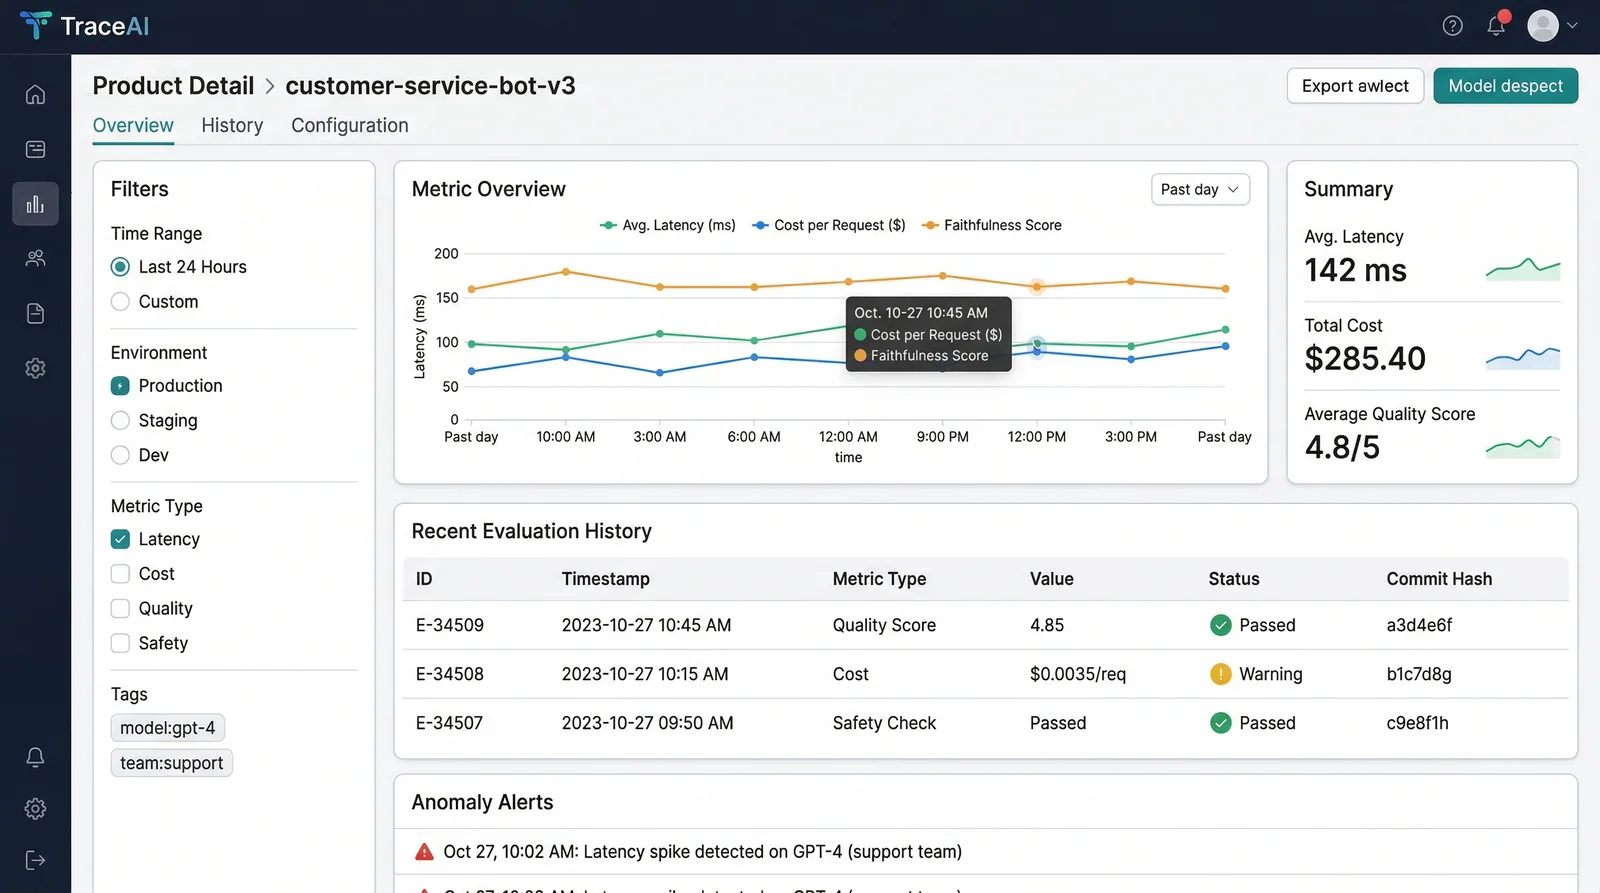
An observability dashboard for AI features in production. It records accuracy, latency, cost and toxicity for every model call, updates live, and is wired into CI so a release that scores below 90% on evaluations does not ship.
- Year
- 2026
- Duration
- 3.5 months
- Type
- Full stack
- Status
- In production
Results
- 10k+ model calls a day
- Dashboard refreshes every 100 ms
- Deploys blocked below a 90% eval score
The problem
Many AI teams ship models without knowing how they behave in production. There is no standard way to track accuracy, latency and cost across thousands of inferences a day, catch quality regressions before users do, or show stakeholders that the system meets its SLAs. Teams usually find out about degradation from user complaints.
What we built
We built an observability platform for AI applications. OpenTelemetry instruments every call, DeepEval scores each inference on 15 quality metrics, and the results go into ClickHouse so dashboard queries return in under 100ms. The same evals run in CI and block a deploy when a score falls below its threshold.
- Live inference monitoring
- OpenTelemetry tracks every LLM call: latency (p50/p95/p99), token usage, cost per inference and error rate. The dashboard refreshes every 100ms.
- 15 evaluation metrics
- DeepEval scores every inference on faithfulness, relevancy, hallucination, toxicity, bias, coherence and 9 more metrics. RAGAS adds RAG-specific quality scores.
- Deploy gates in CI
- Eval suites run as pytest fixtures in the CI pipeline. A PR that pushes any metric below its threshold is blocked, with a report of what regressed.
- Anomaly alerts
- Anomaly detection on rolling metric windows sends PagerDuty and Slack alerts when quality moves more than 2σ from its 7-day moving average.
How it works
Every LLM call is traced and scored. The results feed live dashboards and alerts, and the same evals gate deploys in CI.
- 01
Instrumentation
OpenTelemetry SDK wraps LLM calls → captures latency, tokens, cost and response
- 02
Evaluation
DeepEval runs 15 metrics on each inference → scores stored with the trace data
- 03
Storage
ClickHouse ingests metric events → columnar compression keeps queries on 1B+ rows under 100ms
- 04
Dashboard
Next.js + Tremor render live charts → accuracy, latency, cost and toxicity panels
- 05
Alerting
Anomaly detection on rolling windows → PagerDuty + Slack alerts on quality regressions
- 06
CI/CD gate
pytest eval suites in CI → deploy blocked if any metric drops below its threshold
Screens
Decisions
- ClickHouseData
- We store metrics in ClickHouse rather than TimescaleDB. At 1B+ rows, its columnar compression made aggregation queries 10-50x faster, and dashboard queries that took 3s in Postgres return in 80ms.
- Tremor v3.0Frontend
- Its prebuilt dashboard components already follow the observability UI patterns engineers expect, so we did not need custom D3 charts. It cut frontend development time by 60%.
- OpenTelemetryInfrastructure
- We used OTel rather than custom instrumentation so nobody is tied to one vendor. Teams can send traces to Datadog, Grafana or Jaeger without changing application code, and the semantic conventions keep metric names consistent across services.
- DeepEval 0.4.2AI / ML
- Its pytest integration and ready-made metrics meant we did not have to write our own eval scripts. Eval suites are ordinary test files, so they run on the existing CI without a separate eval platform.
What went wrong
Slow dashboard queries
- Problem
- At 10k+ inferences a day with 15 metrics each, every chart update scanned 150k+ rows. The first version on Postgres took 3-5 seconds to load the dashboard, which is too slow for live monitoring.
- Fix
- We moved metric storage to ClickHouse, with materialized views for the common hourly and daily rollups. The most-viewed panels cache their query results in Redis with a 10-second TTL.
- Result
- Dashboard load time fell from 4.2s to 180ms. Engineers now keep the dashboard open in a tab as their monitoring view.
Eval cost in the request path
- Problem
- Running 15 DeepEval metrics on every inference added 800ms+ of latency and doubled LLM costs, since each metric needs extra LLM calls to make its judgment. That was not acceptable on latency-sensitive production paths.
- Fix
- Evaluation now runs asynchronously. Inference results return immediately, and metrics are computed in a background queue (Celery + Redis). For the CI gates, synchronous evals run on a representative 5% sample instead of every inference.
- Result
- No added latency on production inference. The eval queue runs with a median lag of 12 seconds, which is fast enough for the live dashboard.
Team and stack
Hiroshi designed the architecture and built the Next.js dashboard. Kenta built the OpenTelemetry instrumentation, the DeepEval pipeline and the CI gates. Hiroki built the ClickHouse storage, the rollups and the anomaly alerts.
- Next.js 15
- Tremor
- ClickHouse
- OpenTelemetry
- DeepEval
- RAGAS
- PagerDuty
- Vercel Edge